Updated September 9, 2026.
AI review analysis metrics should tell you whether review analysis helped a team make a better decision. They should not stop at model accuracy, sentiment charts, or the number of reviews processed.
That distinction matters because AI review analysis is usually bought for an operating job: deciding what to fix, what to build, what to rewrite in a listing, what to monitor, or what evidence to send to a product, support, ecommerce, or research owner. A dashboard can look complete while still failing that job.
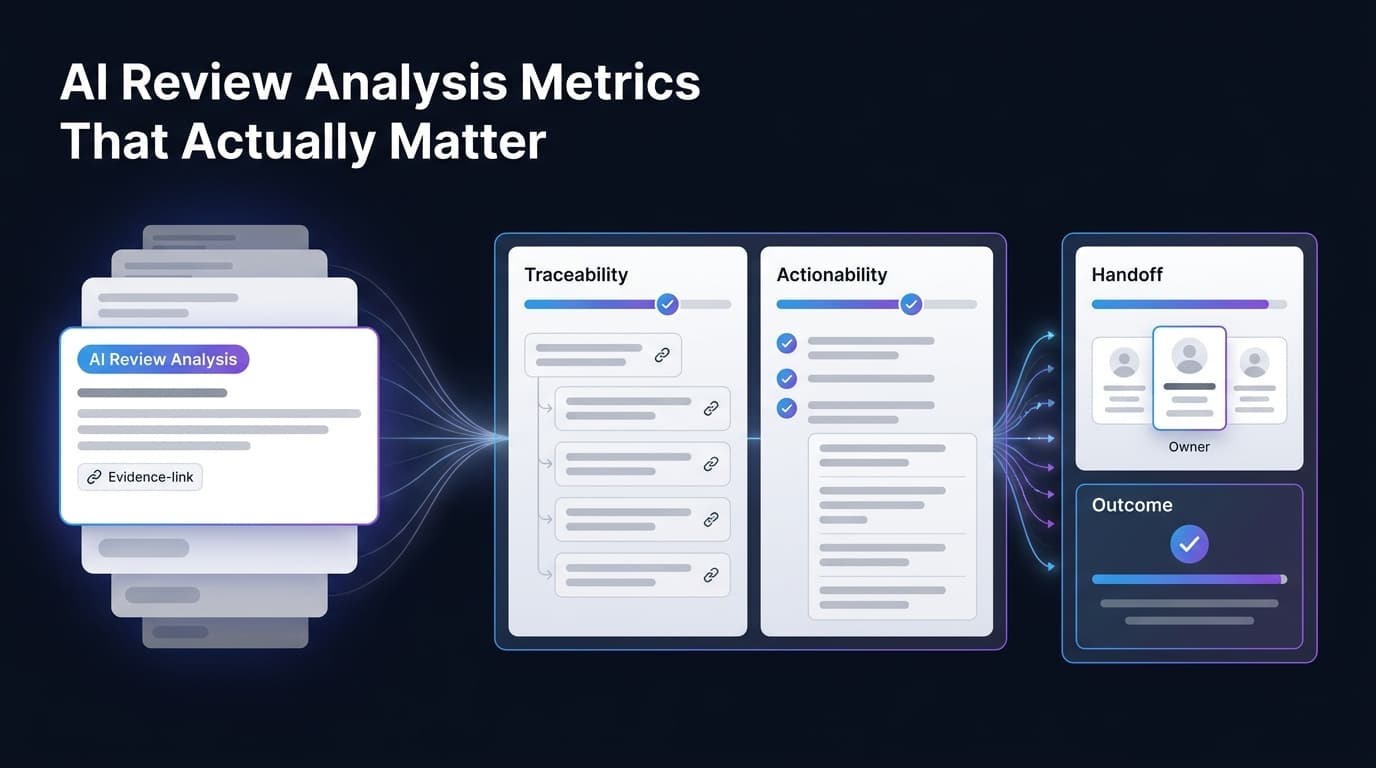
This guide gives you a practical metric stack for AI review analysis: evidence coverage, traceability, theme quality, contradiction handling, severity, decision handoff, time saved, reuse, and downstream action. Use it when you are evaluating AI review analysis tools, reviewing a pilot, or cleaning up an internal review-analysis workflow.
If you are still comparing tool categories, start with the AI review analysis comparison. If you need the operating workflow, use the AI review analysis practical guide. This page focuses on measurement: how to know whether the workflow actually works.
Start with the decision metric
Before you measure any AI review analysis output, write the decision it is supposed to support:
We are analyzing this review cohort so this owner can make this decision by this date.
That sentence keeps the metrics honest. If the decision is "rewrite the product detail page," you need buyer-language coverage, objection evidence, and listing-change handoff. If the decision is "prioritize defects," you need severity, recurrence, recency, affected variants, and traceable examples. If the decision is "compare competitors," you need cohort control and like-for-like theme comparison.
The first metric is decision fitness:
| Metric | How to measure it | Good sign | Warning sign |
|---|---|---|---|
| Decision fitness | Can the output answer the stated decision question without another manual review pass? | The owner can accept, reject, or request one clear follow-up | The output is interesting but nobody knows what to do next |
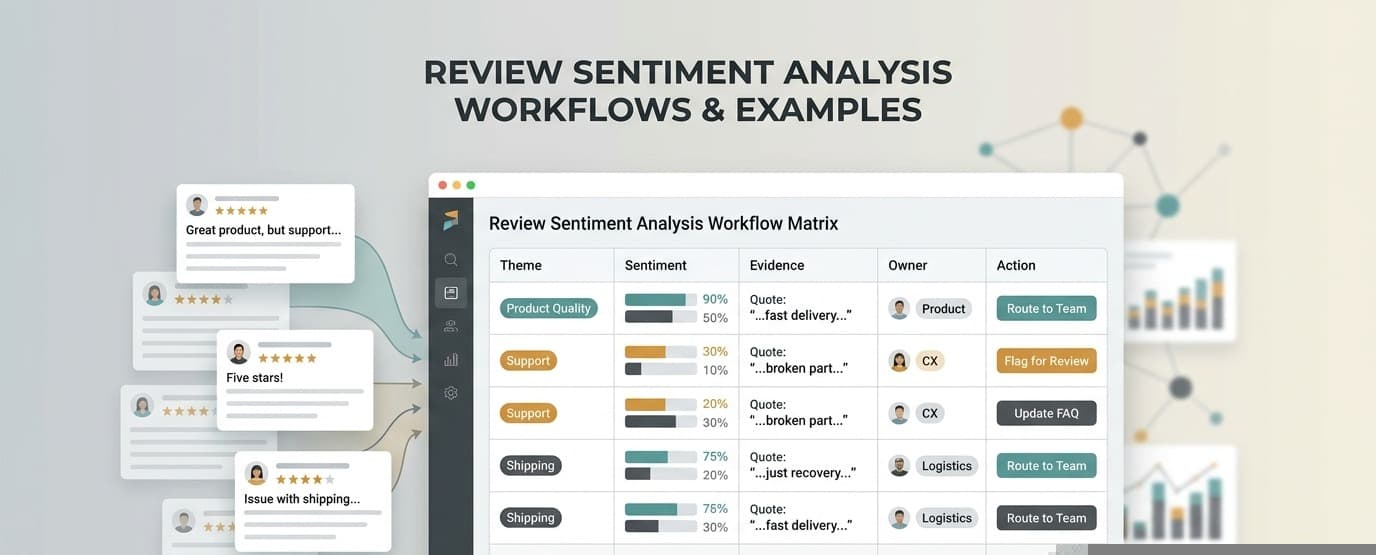
| Owner clarity | Does each finding map to product, listing, support, research, operations, or marketing? | Every top finding has an accountable owner | Themes sit in a shared dashboard with no route |
| Decision date fit | Did the analysis arrive before the planning, launch, support, or review meeting? | Evidence is ready when the team decides | Analysis lands after the decision window has closed |
Do not skip this step. Most weak AI review analysis metrics fail because they evaluate the model in isolation instead of evaluating the decision workflow.
The 10 AI review analysis metrics that matter
Use these metrics as a stack. You do not need every metric on day one, but you do need at least one metric for scope, trust, action, and outcome.
| Layer | Metric | What it protects | What not to optimize |
|---|---|---|---|
| Scope | Evidence coverage rate | The analysis looked at the right review universe | Raw number of reviews processed |
| Trust | Traceability rate | Important claims can be inspected | Polished summary language |
| Signal | Theme precision and coverage | Themes are specific and complete enough to use | Theme count by itself |
| Risk | Contradiction preservation | Segment splits and counterevidence stay visible | Forced consensus |
| Priority | Severity-weighted issue rate | Urgent issues rise above noisy volume | Mentions without consequence |
| Action | Actionability rate | Findings become accepted work | Ideas generated |
| Handoff | Handoff completion rate | Owners receive evidence and next step | Dashboard completion |
| Efficiency | Time saved per accepted decision | The team decides faster without hidden rework | Processing speed alone |
| Compounding | Reuse rate | Outputs become libraries, baselines, or API-fed workflows | One-off report volume |
| Outcome | Downstream outcome linkage | Actions can be reviewed against later signals | Overclaimed attribution |
For a first pilot, choose traceability rate, actionability rate, and time saved per accepted decision. Those three AI review analysis metrics show whether the workflow is trusted, used, and faster.
Metric 1: Evidence coverage rate
Evidence coverage rate asks whether the AI review analysis looked at the right review universe.
Use this formula:
evidence coverage rate = reviews included in analysis / reviews that should be in scope
Scope should be explicit:
- product, ASIN, SKU, variant, plan, feature, or competitor set
- marketplace, channel, region, or language
- date range
- star rating range
- verified-purchase filter, if relevant
- launch, campaign, support incident, or product-version boundary
- excluded sources or segments
For ecommerce teams, this metric matters more than raw volume. An analysis of 10,000 reviews can still be weak if it mixes old packaging complaints with a new variant, combines competitor and first-party reviews without labels, or ignores the one-star cohort that triggered the investigation. The same logic applies when teams compare customer feedback analysis tools: the cohort has to match the decision.
VOC.AI's public Voice of Customer Analysis page frames review analysis around turning customer reviews into product direction, buyer language, and market-ready decisions. The practical point for your own process is simple: measure whether the cohort matches the decision before you trust the themes.
Metric 2: Traceability rate
Traceability rate measures how many important claims can be traced back to source reviews.
Use this formula:
traceability rate = cited or inspectable claims / total important claims
An important claim is any statement that could change a decision:
- "Customers return the product because the lid leaks."
- "The setup instructions are confusing for first-time buyers."
- "Competitor A wins because buyers trust the battery life."
- "The strongest purchase motivation is travel use."
- "Negative sentiment increased after the new packaging."
For every important claim, the AI review analysis should preserve enough evidence to inspect the source. That can be review IDs, quoted snippets, product links, dates, star ratings, exported evidence rows, or another source reference your team can reopen. A summary without evidence may be useful for orientation, but it is not enough for decisions that involve roadmap, listing, support, budget, or operational changes.
Traceability is also where AI review analysis separates itself from simple review summarization. A summary compresses language. Decision-grade AI review analysis keeps the path back to the evidence.
Metric 3: Theme precision and theme coverage
Theme precision asks whether extracted themes are specific enough to use. Theme coverage asks whether the analysis found the important issues in the cohort.
Track both:
| Metric | Question | Strong output | Weak output |
|---|---|---|---|
| Theme precision | Are themes distinct and concrete? | "Lid leaks when packed sideways in a work bag" | "Quality issue" |
| Theme coverage | Did the analysis find the major recurring issues? | Captures leakage, odor retention, replacement-part confusion, and cleaning friction | Captures only generic positive and negative sentiment |
| Theme duplication | Are similar themes merged cleanly? | "Charging port loosens after 3-6 months" is one tracked theme | Same issue appears as port, cable, charging, and durability |
A fast manual benchmark helps. Pull 30 to 50 representative reviews. Ask one product, support, or ecommerce owner to list the top themes. Then compare the AI review analysis against that list. The goal is not perfect agreement. The goal is to catch whether the model misses decision-critical themes or creates vague clusters that cannot be assigned.
Metric 4: Contradiction preservation
Good AI review analysis does not flatten disagreement. It shows where customers are split.
Contradiction preservation measures whether meaningful opposing evidence remains visible:
contradiction preservation = major themes with visible counterevidence / major themes where counterevidence exists
Examples:
- Some buyers say the product is too small; others praise the compact size.
- New users struggle with setup; repeat buyers say setup is simple.
- One-star reviews mention breakage; five-star reviews mention durability after light use.
- US buyers complain about sizing; EU buyers complain about material feel.
This metric matters because many ecommerce and product decisions are segment decisions. A theme may be real but not universal. If AI review analysis hides the split, the team may overcorrect and damage the segment that already likes the product.
Metric 5: Severity-weighted issue rate
Theme volume alone is a poor prioritization metric. A low-frequency safety, refund, compliance-adjacent, or account-risk issue may matter more than a high-frequency minor preference.
Use a severity-weighted view:
severity-weighted issue rate = issue frequency x severity score x recency weight
Keep the severity scale simple:
| Severity | Meaning | Example |
|---|---|---|
| 1 | Preference or wording issue | Buyers dislike a color name |
| 2 | Usability friction | Buyers need clearer assembly instructions |
| 3 | Product defect or expectation mismatch | Buyers report leakage, early breakage, missing parts, or confusing setup |
| 4 | Revenue, support, or retention risk | Buyers mention returns, refunds, churn, escalation, or competitor switching |
| 5 | High-risk escalation | Buyers describe safety, legal, account, privacy, or platform-policy concerns |
Do not ask AI review analysis to make final legal, safety, medical, financial, or compliance judgments. Use it to surface review evidence that needs human review. The metric should help teams prioritize inspection, not automate judgment.
Metric 6: Actionability rate
Actionability rate measures how often AI review analysis produces a finding that can move into a real workflow.
Use this formula:
actionability rate = findings converted into accepted actions / findings reviewed
Accepted actions can include:
- product ticket
- listing copy test
- support macro update
- help-center update
- competitor research follow-up
- monitoring alert
- customer interview prompt
- warranty, refund, or returns investigation
- API-fed dashboard or recurring report
This metric protects the team from insight theater. A report with 40 findings is not necessarily better than a report with six findings if none of the 40 survive review. Track accepted actions, not generated ideas.
Metric 7: Handoff completion rate
Handoff completion rate measures whether the output reached the right owner with enough context.
Use this formula:
handoff completion rate = findings with owner + evidence + next step / total accepted findings
A complete handoff includes:
- owner
- evidence link or review sample
- affected cohort
- severity
- recommended next step
- decision deadline
- follow-up metric
- status
This is one of the most important AI review analysis metrics for teams that already have enough dashboards. The bottleneck is often not finding a theme. The bottleneck is getting the theme into the operating system where work actually happens.
Metric 8: Time saved per accepted decision
Time saved is useful only when it is tied to accepted decisions.
Use this formula:
time saved per accepted decision =
(manual analysis hours - AI-assisted analysis hours) / accepted decisions
Avoid the vanity version: "We analyzed 20,000 reviews in minutes." That may be true and still not prove value. The better question is whether the team reached a decision faster without losing evidence quality.
Track time by workflow:
| Workflow | Time to measure | Why it matters |
|---|---|---|
| Product defect triage | From cohort selection to accepted issue list | Helps product and operations prioritize fixes |
| Listing rewrite | From review pull to approved copy-test brief | Connects review language to conversion work |
| Competitor review analysis | From competitor set to opportunity brief | Helps teams compare like with like |
| Support handoff | From complaint theme to macro or escalation update | Turns review analysis into service improvement |
| Research planning | From raw review evidence to accepted interview prompts | Connects review themes to discovery work |
If AI review analysis saves time but lowers trust, the saving will disappear later in rework. Pair this metric with traceability, theme quality, and contradiction preservation.
Metric 9: Reuse rate
Reuse rate measures whether review-analysis outputs become reusable assets instead of one-off reports.
Use this formula:
reuse rate = outputs reused in later decisions / total completed outputs
Reusable assets include:
- buyer-language banks
- objection libraries
- complaint taxonomies
- competitor evidence matrices
- product requirement notes
- support macro inputs
- review-monitoring baselines
- API-fed dashboards
VOC.AI's Review Analysis API page positions the API around programmatic access to review, keyword, sales, and listing data through API and MCP surfaces. For teams with engineering support, reuse rate is a useful AI review analysis metric because it shows whether review analysis is becoming infrastructure, not just a monthly export.
Metric 10: Downstream outcome linkage
Downstream outcome linkage asks whether accepted findings can be connected to business or product outcomes after action.
This does not mean pretending one review-analysis report caused every result. It means preserving the chain:
review evidence -> accepted finding -> action -> measured outcome
Useful outcome metrics depend on the decision:
| Decision type | Outcome metric to watch |
|---|---|
| Listing change | Click-through rate, conversion rate, return reason mix, question volume |
| Product fix | Defect mentions, replacement requests, rating trend, refund reason mix |
| Support update | Contact rate, escalation rate, first-response quality, repeat contacts |
| Competitor response | Win/loss notes, review-share changes, positioning tests |
| Market research | Accepted hypotheses, launched tests, product discovery cycle time |
Keep the attribution modest. The goal is not to overclaim ROI. The goal is to know whether AI review analysis created a traceable path from customer language to an action the business cared about.
A practical AI review analysis scorecard
Use this scorecard during a pilot or monthly review:
| Scorecard row | Pass condition | Evidence to keep |
|---|---|---|
| Decision sentence | The owner, cohort, decision, and date are named | Decision note or meeting agenda |
| Evidence coverage | Included reviews match the scoped decision | Cohort rule, source count, exclusions |
| Traceability | Major findings link to source reviews | Review IDs, snippets, dates, ratings |
| Theme quality | Themes name behavior, context, and consequence | Theme table and manual sample check |
| Contradictions | Counterevidence and segment splits are visible | Contradiction notes |
| Severity | High-risk findings are escalated for human review | Severity score and escalation owner |
| Actionability | Accepted findings become tickets, tests, alerts, or briefs | Action log |
| Handoff | Each action has owner, next step, status, and review date | Handoff tracker |
| Efficiency | Time saved is measured per accepted decision | Manual vs AI-assisted time log |
| Reuse | Outputs become reusable evidence assets | Library, taxonomy, baseline, or API job |
| Outcome | Follow-up metric is checked after action | Outcome note |
This scorecard is intentionally operational. It should fit into a pilot review, product meeting, support triage, ecommerce weekly review, or research planning session.
How to measure a pilot in 14 days
Run the pilot against one real decision, not a generic demo dataset. The same same-evidence discipline is useful when evaluating adjacent workflows, such as a product research AI tools evaluation framework.
- Define the decision sentence.
- Select the review cohort and save the cohort rules.
- Run the same cohort through the AI review analysis workflow.
- Ask the owner to review the top findings.
- Score traceability, theme quality, contradiction handling, severity, and actionability.
- Convert accepted findings into tickets, tests, alerts, research prompts, or support updates.
- Record time spent by humans before and after AI assistance.
- Review the first downstream signal after the action ships or the investigation closes.
This pilot structure is small on purpose. You do not need a complex analytics program to learn whether AI review analysis is working. You need a decision, a cohort, evidence, an owner, and a follow-up date.
Where VOC.AI fits
VOC.AI is strongest when AI review analysis needs to move from review language into product, listing, market, support, or API workflows.
Use Voice of Customer Analysis when the team needs review themes, buyer language, pain points, expectations, and decision-ready outputs from customer review evidence. Use Review Analysis API when the same signals need to flow into an internal dashboard, agent, report, or recurring workflow. Use Pricing when the team is choosing between a trial, review analytics platform workflow, or API/MCP subscription path.
That matters for the metrics in this guide. Evidence coverage, traceability, handoff, reuse, and downstream linkage are easier to manage when review analysis is not trapped in a one-off summary. The point of AI review analysis is not to produce a prettier report. It is to keep customer evidence close enough to the workflow that teams can act on it.
FAQ
What is the most important AI review analysis metric?
Traceability rate is the first metric to check. If important findings cannot be traced back to source reviews, teams will struggle to trust the analysis or defend the decision.
Is model accuracy enough to evaluate AI review analysis?
No. Accuracy matters, but it is incomplete. AI review analysis also needs evidence coverage, theme specificity, contradiction handling, owner handoff, and downstream action.
How many reviews should I use to test an AI review analysis tool?
Use enough reviews to represent the decision cohort. For a quick benchmark, manually inspect 30 to 50 representative reviews, then compare the AI output against the themes and evidence an owner found important.
Should sentiment score be a primary metric?
Sentiment score is useful for orientation, but it should not be the primary decision metric. Teams usually need to know what customers are saying, why it matters, where the evidence is, and what action should follow.
How do I avoid vanity metrics in AI review analysis?
Tie every metric to a decision. Reviews processed, charts generated, and themes created are weak metrics unless they lead to traceable findings, accepted actions, or reusable workflow assets.
When should AI review analysis use an API workflow?
Use an API workflow when the same review signals need to refresh repeatedly, feed another system, or support a team workflow outside a standalone dashboard. If the analysis is a one-time decision with a small review set, a manual workflow may be enough.
Conclusion
The AI review analysis metrics that actually matter are the ones that protect the decision: did the system analyze the right cohort, preserve the evidence, find specific themes, show contradictions, prioritize severity, route findings to owners, save time, and connect actions to outcomes?
Start with traceability rate, actionability rate, and time saved per accepted decision. Then add evidence coverage, contradiction preservation, handoff completion, reuse, and downstream linkage as the workflow matures.
That is how AI review analysis becomes an operating system for customer evidence instead of another dashboard nobody trusts.